01 / SCOPE & PURPOSE
Build a cross-tabulation from detailed records
A CSV Pivot Table Maker summarizes records at the intersection of row categories and column categories.
Create a CSV pivot table with multiple metrics, direct totals, size checks, and cell-level source details.
Import data, confirm the rules, review the result, and export a new copy.
Drag and drop a CSV, TSV, or delimited text file
UTF-8 · Up to 10 MB per fileExplore the scope, review process, and results in three practical scenes.
A CSV Pivot Table Maker summarizes records at the intersection of row categories and column categories.
An unobserved intersection is blank by default.
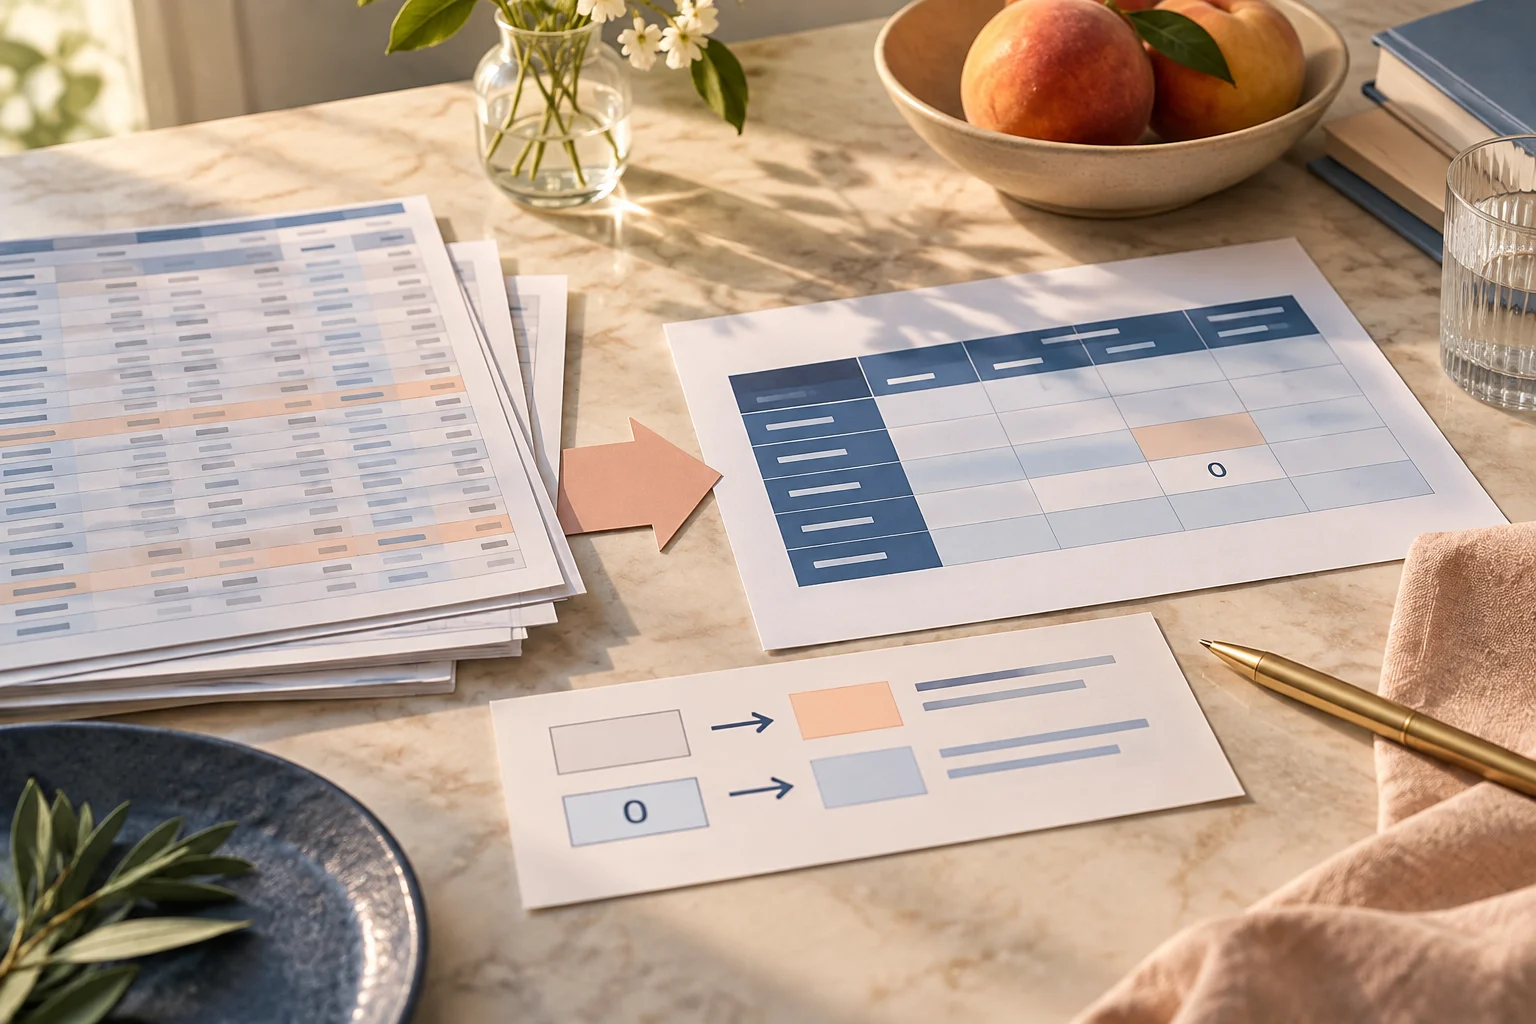
Export new copy produces CSV or TSV, not a screenshot.
Explore the available features and choose what your table needs next.
A CSV Pivot Table Maker summarizes records at the intersection of row categories and column categories.
Use in the toolUse Choose files for UTF-8 CSV or TSV or Paste a table for copied spreadsheet data.
Use in the toolAggregation begins with Record count.
Use in the toolImport four detail records: East in January with ten, East in January with twenty, East in February with five, and South in January with seven.
Use in the toolAn unobserved intersection is blank by default.
Use in the toolRow totals aggregate all participating observations in the row category.
Use in the toolConfirm the input, inspect changes, and save the output you need.
Choose a CSV or TSV file, or paste a table. Check the delimiter, headers, and preview before confirming the full import.
Create a CSV pivot table with multiple metrics, direct totals, size checks, and cell-level source details.
Choose the result or report and CSV or TSV format. Review the export summary and protection count, then confirm download or copy.
A CSV Pivot Table Maker summarizes records at the intersection of row categories and column categories. Regions can become rows, months can become columns, and sales amounts can become the values inside the table. Multiple records at one intersection are combined by the selected aggregation. This creates a cross-tabulation from observations. It differs from transposing a table, which exchanges existing row and column positions without calculating new grouped values.
A pivot is useful when a long transaction table needs to become a compact comparison across categories. It is less suitable when the column field contains a different value for nearly every record. Using an individual transaction identifier as the column category can produce an extremely wide table. Plan the intended dimensions first: choose a meaningful row population, a manageable set of column categories, and metrics whose units and denominators you understand.
Use Choose files for UTF-8 CSV or TSV or Paste a table for copied spreadsheet data. Confirm headers and delimiters before configuring the pivot. The tool does not load workbook sheets or interpret spreadsheet cell formatting. If the source is a workbook, export the intended sheet and data range as a supported text table first, checking that the resulting values have the intended meaning. Decorative report headers and subtotals should not accidentally become transaction records.
Row fields and Column fields accept one or more selected columns. The order of selection defines each composite category. Source strings remain exact: North and north are distinct, and leading-zero identifiers retain their text. Categories are not automatically trimmed or standardized. If several spellings should share one category, confirm that mapping in the standardization tool before pivoting. An explicit preparatory step makes the resulting aggregation explainable instead of hiding a silent category merge.
Aggregation begins with Record count. It counts observations at each row-and-column intersection and does not require a numeric value field. Add metric can create Nonempty count, Distinct count excluding empty values, Sum, Mean, Minimum, or Maximum. Each metric has its own Result column name. Several metrics can inspect one source field or different source fields, allowing a pivot to display both transaction counts and total amounts.
Numeric metrics require confirmed numeric interpretation. Select the amount field and establish its decimal separator, grouping separator, sign notation, permitted currency markers, and percentage semantics. A numeric-looking identifier should not become a measurement merely because it can be parsed. The shared decimal path preserves supported exact values and avoids a binary-floating-point sum such as an unexpected approximation to 0.3 for 0.1 plus 0.2. Existing normalized columns can carry their confirmed interpretation into these controls.
Import four detail records: East in January with ten, East in January with twenty, East in February with five, and South in January with seven. Choose region as the Row field, month as the Column field, and Sum of amount as the metric. East and January contains thirty because both detail records contribute. East and February contains five, South and January contains seven, and South and February is blank because no record was observed there.
With Row totals and Column totals enabled, East totals thirty-five, South totals seven, January totals thirty-seven, February totals five, and the grand total is forty-two. Opening the East-January result cell reveals both contributing detail records rather than selecting one arbitrary input. The synthetic sample library includes this case, an observed-zero boundary case, and an invalid-number case so you can verify the meaning of the controls before applying them to another file.
An unobserved intersection is blank by default. A real observation with amount zero can produce the numeric result zero, which carries different information. Fill unobserved combinations with zero is an explicit output option. It changes how absent combinations are represented in the exported table, but does not insert new observations into the underlying data. Consequently, enabling this setting does not expand the denominator of a mean or alter a count calculated from the original records.
A third condition occurs when an intersection has observations but none contain a valid numeric value. Its sum or mean remains blank, with missing and invalid values governed by their respective policies. Do not equate an absent combination, an observed empty amount, an invalid amount, and a measured zero. They may all need different follow-up decisions. The source-detail view and numeric-issue report let you distinguish them instead of relying only on the appearance of the final cell.
Row totals aggregate all participating observations in the row category. Column totals aggregate all observations in the column category. The grand total aggregates the complete participating population. Means and distinct counts are recalculated at each level, not obtained by adding or averaging the displayed cells. This matters when intersections contain unequal numbers of records or when the same customer identifier appears in more than one category.
For example, one intersection containing ten has a mean of ten, while another containing twenty, twenty, and twenty has a mean of twenty. Their combined mean is 17.5, based on four observations. A simple average of the two cell means would give fifteen and would be wrong for that population. Similarly, if one customer appears in January and February, each monthly distinct count may be one while the overall distinct count remains one. Totals must preserve the metric's definition rather than its display arrangement.
Before generating the full pivot, the engine determines the observed row and column category counts and projects the output dimensions, including every metric and requested total. The number of output columns grows with column-category combinations multiplied by metric count. Row-key fields and row-total columns also occupy space. The configured guards cap the output at two hundred columns and enforce row and total-cell limits. An oversized result is blocked rather than partially produced and described as complete.
Reduce the number of column fields, choose a less granular category, filter the input explicitly, or use an ordinary grouped summary when the projected width is too large. A sample result does not justify an unlimited full pivot: expansion checks still consider the full input's categories. Result tables scroll inside the grid instead of widening the whole page. This helps inspect supported wide outputs, but does not make a table with thousands of separate categories a useful reporting design.
Output row order and Column order can follow first appearance or sort complete category keys. The engine generates stable pivot column identifiers and a separate mapping from each output column to its original category combination and metric. Generated labels therefore cannot silently overwrite each other when source categories contain punctuation or resemble another combination. The pivot-row report identifies row categories and marks the total row explicitly, including cases where a genuine source row category is empty.
Click a result cell to inspect its contributing records and count. Row source links cover the row population, while cell source links use that particular intersection or total. Numeric issues identify invalid source values separately. The default invalid-number policy blocks complete result export; you can instead explicitly choose exclusion and retain its count and report. Do not call an excluded-value pivot a complete sum of every original amount without disclosing the excluded observations.
Export new copy produces CSV or TSV, not a screenshot. Choose the result, a column or row mapping, numeric issues, or the settings report. The complete bundle keeps those definitions together. Generated files are read back to check rows, fields, and values before Confirm download becomes available. Formula-prefix protection is visible and reports its impact. Category labels and source text may require explicit text import in a receiving spreadsheet to prevent its own automatic numeric or date interpretation.
A full successful pivot can be applied to the workflow and passed to another tool. Undo restores earlier detail-level data through the retained step history. Save rules preserves dimension selections, metrics, numeric conventions, sorting, blank-output policy, and totals. A sample download remains labeled as such and cannot be applied to the full workflow. Changing a field or metric makes previous results stale. Cancel task stops the active worker; refresh or closing clears the page session, so export the tables and rules you need to retain.
Select the category as a row dimension and the month as a column dimension, then choose the value field and aggregation. Repeated row-and-column combinations need an aggregation rule. Review the projected output width and inspect totals; a missing cell, a zero, and an average over available values are not interchangeable.
A pivot groups detail records by row and column categories and aggregates their values. Transpose exchanges existing rows and columns without performing that grouping or aggregation.
All matching records participate in the selected metric. The tool does not arbitrarily keep the first record. Open the result cell to inspect those sources.
No. That option changes the output representation of unobserved combinations. Means and totals still use the original participating observations.
Each column-category combination creates columns for all selected metrics. The engine estimates the resulting dimensions before allocation and blocks outputs beyond the configured limits.
Start with a sample to learn the workflow, then process your own files.