01 / SCOPE & PURPOSE
Split one CSV column while keeping each record together
A packed field is useful for display but awkward for filtering.
Split a CSV column by delimiter or display-character position while preserving source text.
Import data, confirm the rules, review the result, and export a new copy.
Drag and drop a CSV, TSV, or delimited text file
UTF-8 · Up to 10 MB per fileExplore the scope, review process, and results in three practical scenes.
A packed field is useful for display but awkward for filtering.
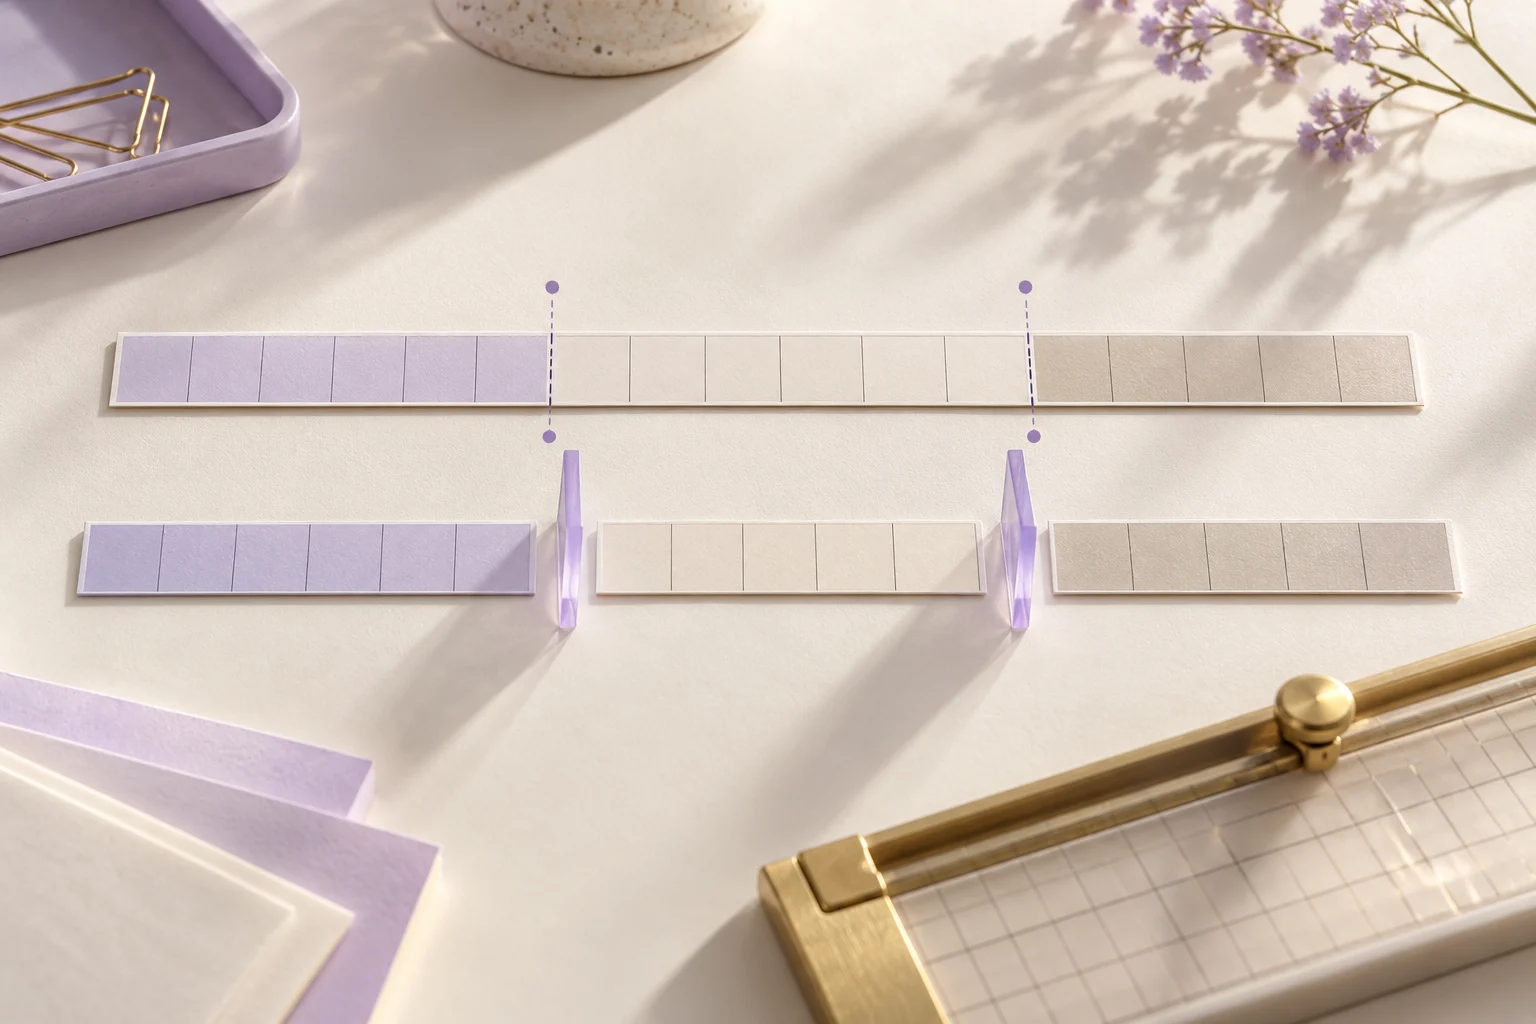
Character positions are useful when every code has a genuinely fixed structure.
Export new copy opens an explicit choice of result or report, CSV or TSV, headers, UTF-8 BOM, and formula-prefix protection.
Explore the available features and choose what your table needs next.
A packed field is useful for display but awkward for filtering.
Use in the toolChoose files, drag a UTF-8 CSV or TSV onto the input area, or use Paste a table.
Use in the toolAll splits at every occurrence of the literal delimiter.
Use in the toolCharacter positions are useful when every code has a genuinely fixed structure.
Use in the toolDestination names must be nonempty and distinct from one another and from existing names.
Use in the toolStart with an id field containing 00123 and a code field containing SKU001-Blue-L.
Use in the toolConfirm the input, inspect changes, and save the output you need.
Choose a CSV or TSV file, or paste a table. Check the delimiter, headers, and preview before confirming the full import.
Split a CSV column by delimiter or display-character position while preserving source text.
Choose the result or report and CSV or TSV format. Review the export summary and protection count, then confirm download or copy.
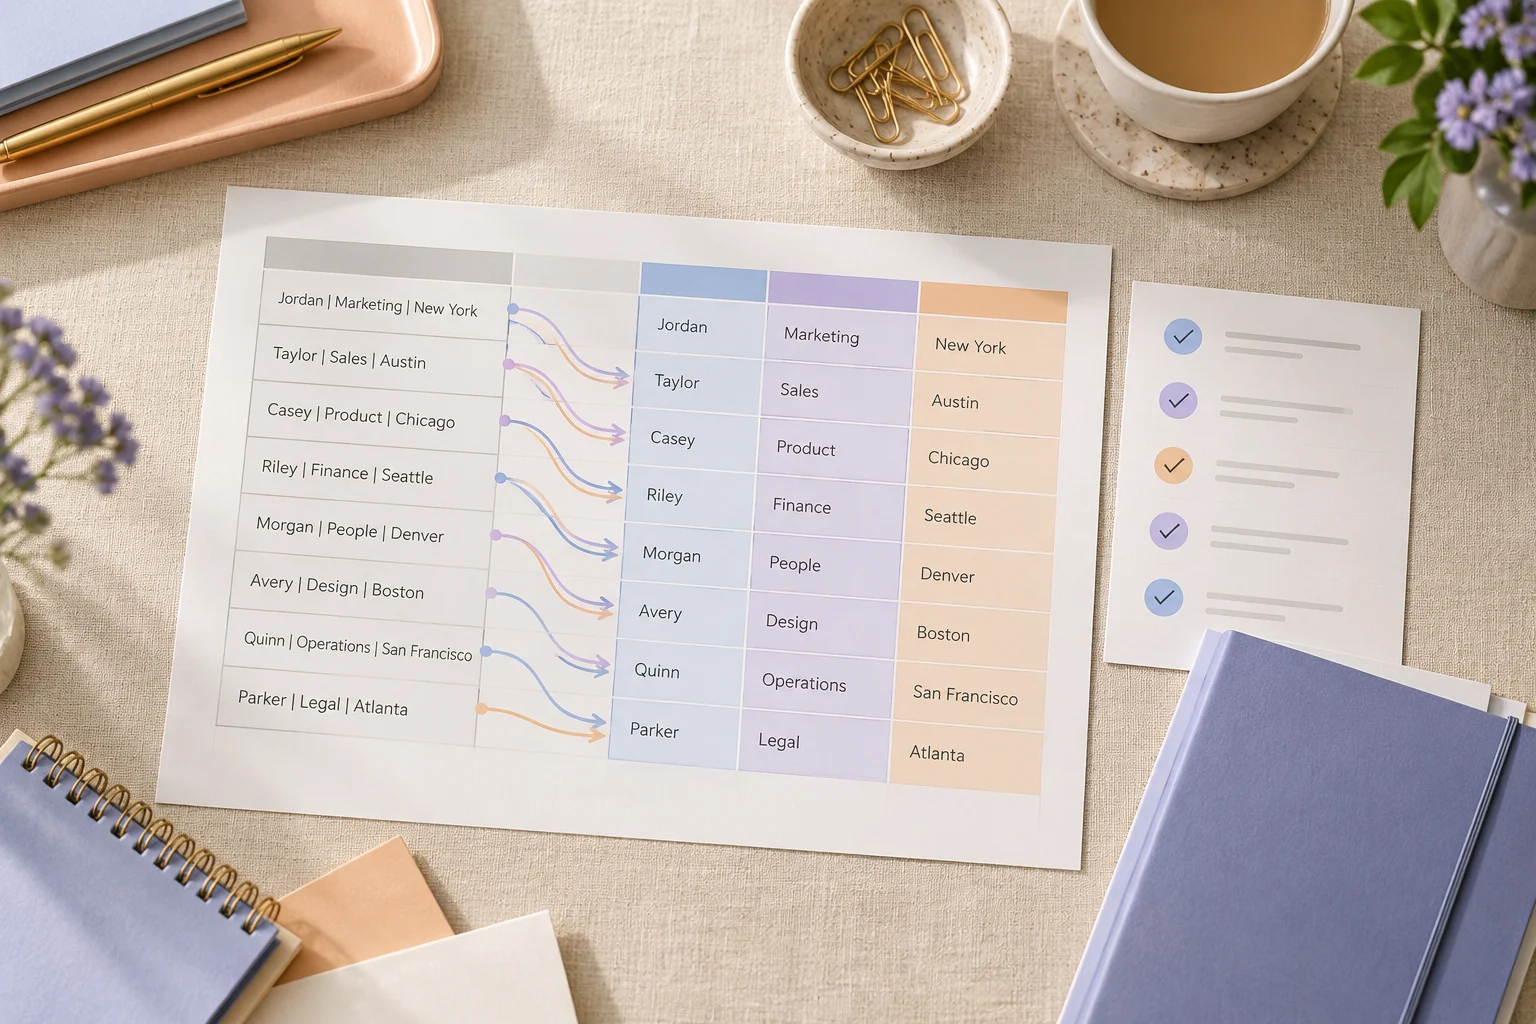
A packed field is useful for display but awkward for filtering. A product code such as SKU001-Blue-L contains three distinct pieces of information. This tool places those pieces in separate destination columns without changing the number or order of records. The original field remains in the result by default, so you can compare every new value with its source before removing anything. Identifiers in other columns, including leading zeros and long digit strings, remain text.
Use this workflow when the structure inside a cell is known. A hyphen between product attributes, a tab between copied values, or a line break between address fragments can be a useful boundary. The boundary must describe the data itself. A comma inside a quoted CSV field is already part of the cell after parsing; it is not confused with the comma separating fields in the file. Splitting a column is separate from dividing a file into downloads or creating additional records.
Choose files, drag a UTF-8 CSV or TSV onto the input area, or use Paste a table. Confirm file parsing opens before any transformation. Review the header and delimiter, select Parse and preview, and check that a multiline description occupies one logical record. Confirm import validates the whole input. If repeated or blank headers are reported, provide distinct names in the parsing dialog instead of letting a destination silently overwrite an existing field.
Choose Source column and Split method. In delimiter mode, pick a Delimiter preset or enter literal characters in Custom delimiter. The custom field accepts a string of several characters, not a regular expression. Enter one destination name per line. The number of names determines the number of output fields. Set Insert new columns to the start, after the source, or the end. Keep source columns is enabled initially and is the safest starting point for review.
Select Preview sample and estimate to see up to twenty output records. That sample does not establish that every later record fits the same pattern. Select Run and review to execute the configuration against the entire table. A late record with too many fields blocks the operation unless you explicitly chose to merge the remainder. After a successful run, inspect Structure issues and Field mapping as well as the main table. Apply to workflow makes the reviewed result available to the next operation.
All splits at every occurrence of the literal delimiter. First only separates the first piece from the remainder. Last only separates the last piece from everything before it. Limit splits accepts a positive maximum and leaves the remaining text together after that many boundaries. For A-B-C, First only and a maximum of one both produce A and B-C. Last only produces A-B and C. Those are different interpretations of the same source and should be chosen deliberately.
Consecutive boundaries have their own setting. With Collapse consecutive delimiters off, A--B becomes A, an empty string, and B. This keeps the fact that a middle value was absent. Turning collapse on treats the consecutive interior delimiters as one boundary. Leading and trailing boundaries can still represent empty edge fields. Collapsing is useful for irregular spacing in some exports, but it changes the structure. Compare the source and result before deciding that repeated separators are merely decoration.
A record containing no delimiter is still a valid record. Its original content enters the first destination, and the remaining destinations are empty. It contributes to the Unsplit records count. A result can also have a short field count because its pattern has fewer parts than the configured names. These categories can overlap; do not add all diagnostic counters together as if each described a separate population. The input and output record totals should remain equal.
Character positions are useful when every code has a genuinely fixed structure. Positions are increasing boundaries after the specified number of complete display characters. Entering 3 and 6 splits after the third and sixth characters. The counting rule uses grapheme clusters, keeping a joined family emoji or a letter with a combining accent intact. It does not count UTF-8 bytes or slice between surrogate halves. This same display-character rule is used by the text extraction tool.
Fixed positions do not understand the meaning of a name, language, or address. A short value can produce an empty segment, and a long value can leave a substantial final segment. Inspect records near both ends of your input and include unusual characters in your sample. If a supplier changes the code format, a previously sensible position rule can become semantically wrong even though the operation still runs. Retain the source and compare representative records whenever the source format changes.
Destination names must be nonempty and distinct from one another and from existing names. This prevents accidental replacement of a field that happens to be called part_1. Rename the new field rather than expecting the tool to choose which copy you meant. Existing columns keep stable internal identities when new fields are inserted, so a later saved step continues to refer to the intended column after a reorder or rename within the workflow.
Too many pieces are never silently discarded. The default behavior reports the problematic source and the required width. Add enough names and run again. Alternatively, choose Merge remaining content into the last column. In delimiter mode the remaining pieces are rejoined with the selected delimiter; in fixed-position mode they are concatenated. This option is useful for a known free-text tail, but it is a deliberate structural decision. The final destination may then contain more than one logical component.
Start with an id field containing 00123 and a code field containing SKU001-Blue-L. Select code, use a hyphen, choose All, and name three destinations sku, color, and size. Keep the source and insert after it. The output retains id and code and adds SKU001, Blue, and L. The record count remains one. A second source value SKU002--M has an empty color with collapse disabled. A third value SKU003 remains available as the first part instead of disappearing.
Review those three patterns together before processing a supplier file. If a note contains an additional bracketed order number, use Extract Text from CSV Columns next. If the new fields need a display label, use Concatenate CSV Columns after applying the split. Column mapping can rename or reposition reviewed fields. Keeping these actions as separate steps makes it possible to undo a formatting decision without discarding the original imported file.
Export new copy opens an explicit choice of result or report, CSV or TSV, headers, UTF-8 BOM, and formula-prefix protection. Verify and review export summary serializes the selected table and parses it again before download becomes available. Protection can add an apostrophe to a value beginning with a formula-like character, including a legitimate negative number. The summary reports the impact. Choosing original text instead requires acknowledging that spreadsheet software may interpret it differently.
The text 00123 is preserved in an unmodified exported field, but double-clicking a CSV in another program can still make that program infer a number. Import identifier columns as text in the receiving application. Current guards limit records, columns, field length, total cells, and processing time; expansion of columns can exceed a guard even when the input file fits. A blocked run leaves the source intact. Cancel task stops the worker. Changing a rule makes a prior result stale and disables export until another full run finishes.
First import the CSV correctly so that quoted commas remain inside their original cell. Then select that column and use the cell’s separator as the split delimiter. Choose the split position and expected part handling, and review rows with missing or extra parts. File parsing and splitting text inside a field are separate steps.
Choose Last only. A-B-C becomes A-B and C. First only produces A and B-C. Both modes preserve the remaining text as one component.
Short records are padded with empty destinations. Overflow blocks by default. Add names or explicitly merge the remainder into the final destination; no extra part is silently discarded.
Keep source columns is enabled initially. Turn it off only after reviewing the new fields. The imported source and applied-step history remain available in the current session.
No. Spaces and name order do not have one universal meaning. Use a rule that matches your source convention and review names with multiple spaces, particles, or unexpected lengths.
Start with a sample to learn the workflow, then process your own files.