01 / SCOPE & PURPOSE
Make version changes visible
Stop scanning two versions row by row. Match records by chosen fields and inspect additions, removals, changes, and unchanged records separately.
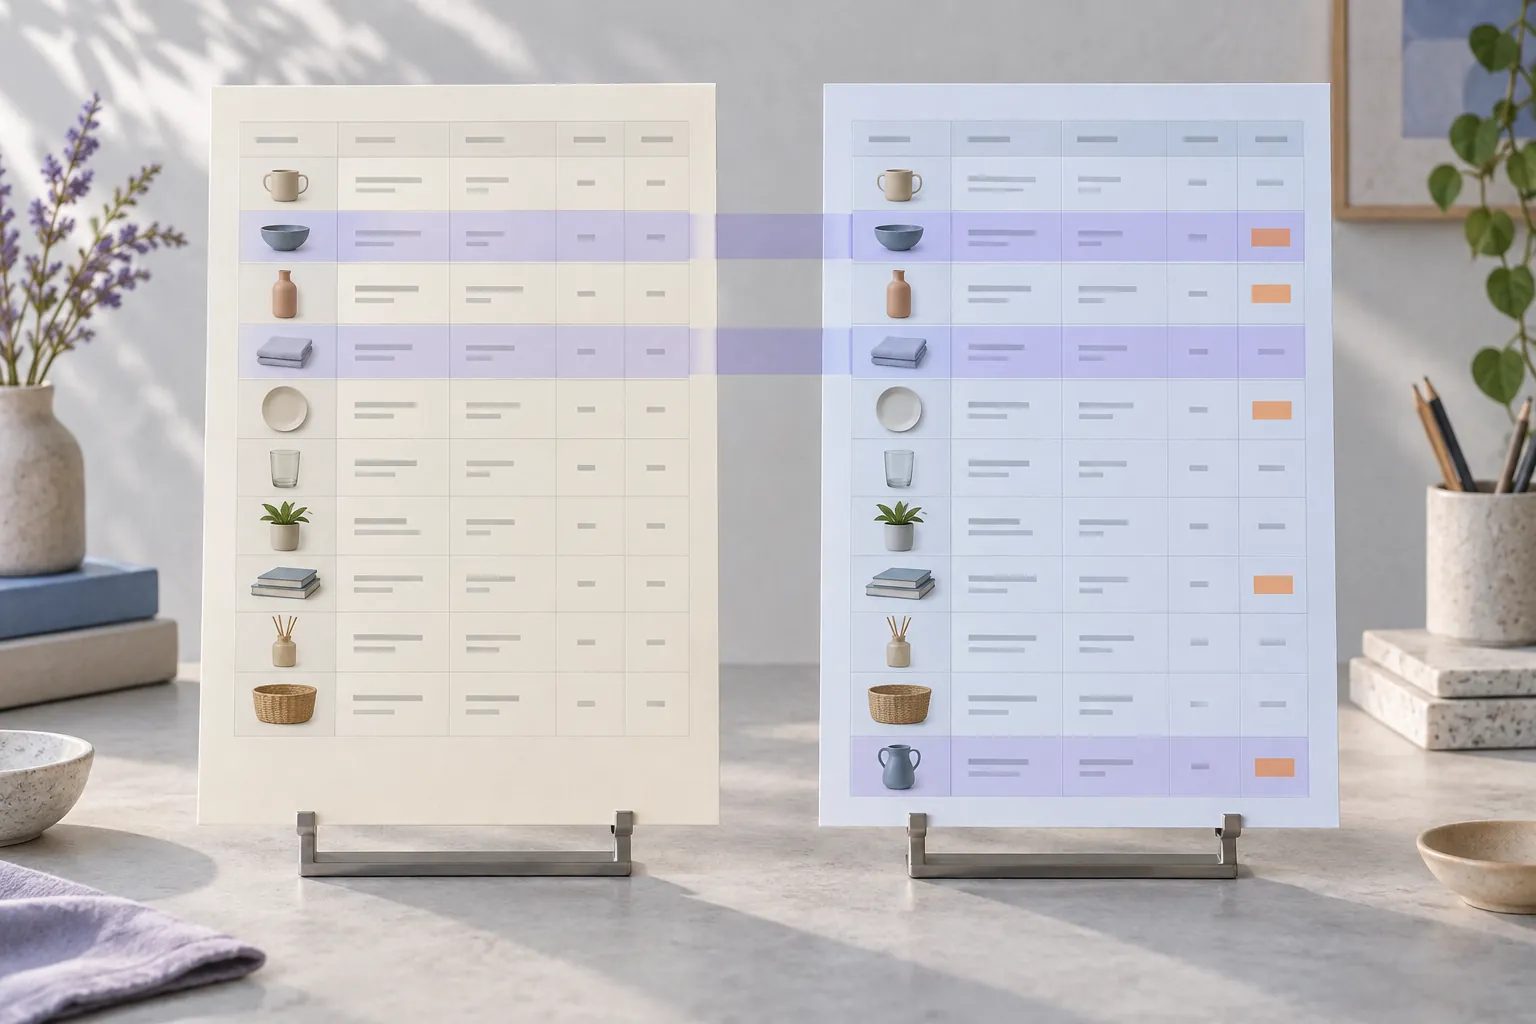
See additions, removals, and edits separately. Review added, removed, modified, and unchanged records by key.
Import data, confirm the rules, review the result, and export a new copy.
Drag and drop a CSV, TSV, or delimited text file
UTF-8 · Up to 10 MB per fileExplore the scope, review process, and results in three practical scenes.
Stop scanning two versions row by row. Match records by chosen fields and inspect additions, removals, changes, and unchanged records separately.
Choose the identifier that represents the same record in both files. Duplicate or missing keys require attention instead of forcing a match by row position.
Inspect old and new values alongside source locations. Export an explicitly chosen report or the available result set for review and follow-up.
Explore the available features and choose what your table needs next.
Match on one or more fields instead of relying on row order.
Use in the toolSeparate added, removed, modified, and unchanged records.
Use in the toolSee old and new field values instead of only knowing that a row changed.
Use in the toolMissing or duplicate matching keys stop the comparison and explain the issue.
Use in the toolTrace differences back to their sources and download matching-issue reports.
Use in the toolChoose the report you need. Searching the visible grid does not reduce the export scope.
Use in the toolConfirm the input, inspect changes, and save the output you need.
Choose a CSV or TSV file, or paste a table. Check the delimiter, headers, and preview before confirming the full import.
Choose the original and updated files and assign stable matching keys. Review each difference category. Missing or duplicate keys block ambiguous comparisons and produce an issue report.
Choose the result or report and CSV or TSV format. Review the export summary and protection count, then confirm download or copy.
Comparing two CSV files is a question about what changed between snapshots. TableWorkbench distinguishes an Original file from an Updated file and classifies records as added, removed, modified, or unchanged. A record's position is not its identity when you choose key comparison. Moving a product from the first row to the last row therefore does not create a change by itself. You select the fields that identify corresponding records and the fields whose values matter for this comparison.
Begin by importing each snapshot and confirming its parsing independently. Two exports can use different delimiters or column orders while still describing the same records. Check that identifiers are read as text, that the first actual product has not become a header, and that multiline descriptions remain intact. The workbench validates the complete parsed input rather than treating a successful first-page preview as proof that the rest of a file is valid. Errors are reported without silently dropping troublesome records.
Select one or more matching columns in each file. Their names can differ, but their meanings and selection order must correspond. For example, a composite key of Store and SKU can distinguish a product sold in two branches. Every selected component must be present, and each combined key must be unique within each snapshot. The tool checks these conditions across all records before producing a deterministic key-based comparison.
A repeated key or an empty component blocks comparison and produces an issue report with source locations. The tool does not arbitrarily pair the first repeated record with another repeated record. You can inspect duplicates in the dedicated deduplication tool, correct the source, or choose a more complete key. Position comparison is available as an explicit alternative, but it means comparing the first record with the first, the second with the second, and so on. It is appropriate only when order itself is the intended correspondence.
Leave the comparison-column selection empty to compare all shared column names, or select only the columns relevant to your question. Excluding a changing export timestamp can prevent that administrative field from dominating a product review. Different column positions are aligned by name, and a manual mapping can connect differently named fields. Added and removed columns are listed in a separate structure report so a schema change is not disguised as thousands of ordinary cell modifications.
Strict text equality is the default. The strings 12.00 and 12.0 differ, as do Blue and blue or a value with a trailing space. Ignore case and Trim surrounding whitespace are explicit options. They affect matching and equality checks without rewriting the stored originals. This version does not interpret currency tolerances, ambiguous dates, or numeric equivalence. If those semantics are necessary, define and validate a separate conversion process instead of assuming that visually similar values are interchangeable.
Added means a key appears in the updated snapshot but not the original. Removed means it appears in the original but not the updated. These describe file membership; they do not prove that an item was created or deleted in a live business system. A filtered source export, an access change, or an incomplete extraction can also change membership. Interpret the result with knowledge of how both snapshots were produced.
Modified means a matched record differs in at least one selected shared field. The modification report has one row for each changed field, retaining its old value, new value, and source positions on both sides. One modified record can therefore produce several report rows. Unchanged means the selected fields match under the chosen rules; an excluded column can still differ. Keep the configuration with your analysis when that distinction matters to another reviewer.
The synthetic original catalog contains SKUs 001, 002, and 003. SKU 001 has price 12.00. The updated catalog contains 003 first, then 001 at price 12.50, then the new SKU 004. Its columns are also reordered. Select SKU as the key on each side and compare the shared fields. The expected outcome is one added record, one removed record, one modified record, and one unchanged record.
SKU 003 is unchanged despite moving. SKU 001 contributes a price change from 12.00 to 12.50. SKU 002 belongs to the removed report, and SKU 004 belongs to the added report. Four classified product identities do not mean either input had four records: each input still had three. Reverse the original and updated selectors and additions become removals, removals become additions, and the price change reverses its old and new values. Comparing either file with itself produces no modifications.
Result tabs provide separate views for added, removed, modified, unchanged, structure changes, and the complete updated table. The complete table is provided for continued processing; it is not declared to be a corrected or authoritative answer. Apply it to the workflow only when you intend to continue working with the updated snapshot. The reports remain the evidence for the comparison you ran. If a rule or input changes, the previous result becomes stale and needs another run before export.
The export dialog asks you to choose scope independently of the visible tab and grid search. Select a single report when you need only new records, or an archive when you need the collection of results and the file manifest. The modified report retains both old and new values. Choose protection deliberately: spreadsheet-safe output adds an apostrophe to formula-like prefixes, while raw output requires acknowledging that another program might execute such text as a formula. Generated text is reread before download to validate serialization.
Use key-based comparison with a stable, unique identifier or field combination. The tool can match records regardless of their positions, then compare the selected fields. Resolve blank or duplicate keys first. Choose position-based comparison only when row positions themselves carry meaning for your task.
Yes, in key mode. Correspondence is established from the selected key fields rather than row positions. A reordered but otherwise identical dataset should produce no modified records. If you select position mode, row order becomes significant by definition. Check the mode before interpreting a large set of differences caused by sorting one input.
Consider whether several existing fields together form a stable unique key. A name alone may not be sufficient. If no such combination exists, use position comparison only when the ordering has a reliable meaning, or improve the source data first. The tool cannot infer real-world identity from similar text, and it does not manufacture an identifier to claim certainty.
Yes. Select the relevant value columns while retaining the fields needed to match records. A matched record is then classified as unchanged when those selected values agree, even if an unselected description differs. This is a scoped comparison, not a statement that every cell in both files is identical. Document the selected fields when sharing the results.
The summary counts modified records. The report records individual field differences, so a product with a changed price and description contributes two report rows but one modified record. Source locations and field names make the relationship inspectable. This is deliberate and avoids squeezing multiple changes into an opaque combined text cell.
A zero-change result means the selected data and rules found no differences. It does not verify that both exports are complete, current, authorized, or correct in the source system. This tool prepares and compares files; it is not a financial audit or a system-of-record certification. Check extraction conditions and the scope before drawing broader conclusions.
Start with a sample to learn the workflow, then process your own files.