01 / SCOPE & PURPOSE
Match keys and add information
Need prices beside products or regions beside names? Match a shared identifier to bring fields from another table into the same record.
Use a shared key to connect two tables. Match keys to bring columns from two tables together.
Import data, confirm the rules, review the result, and export a new copy.
Drag and drop a CSV, TSV, or delimited text file
UTF-8 · Up to 10 MB per fileExplore the scope, review process, and results in three practical scenes.
Need prices beside products or regions beside names? Match a shared identifier to bring fields from another table into the same record.
A key that appears more than once can multiply joined records. Inspect duplicate keys and projected output, then explicitly confirm before proceeding.
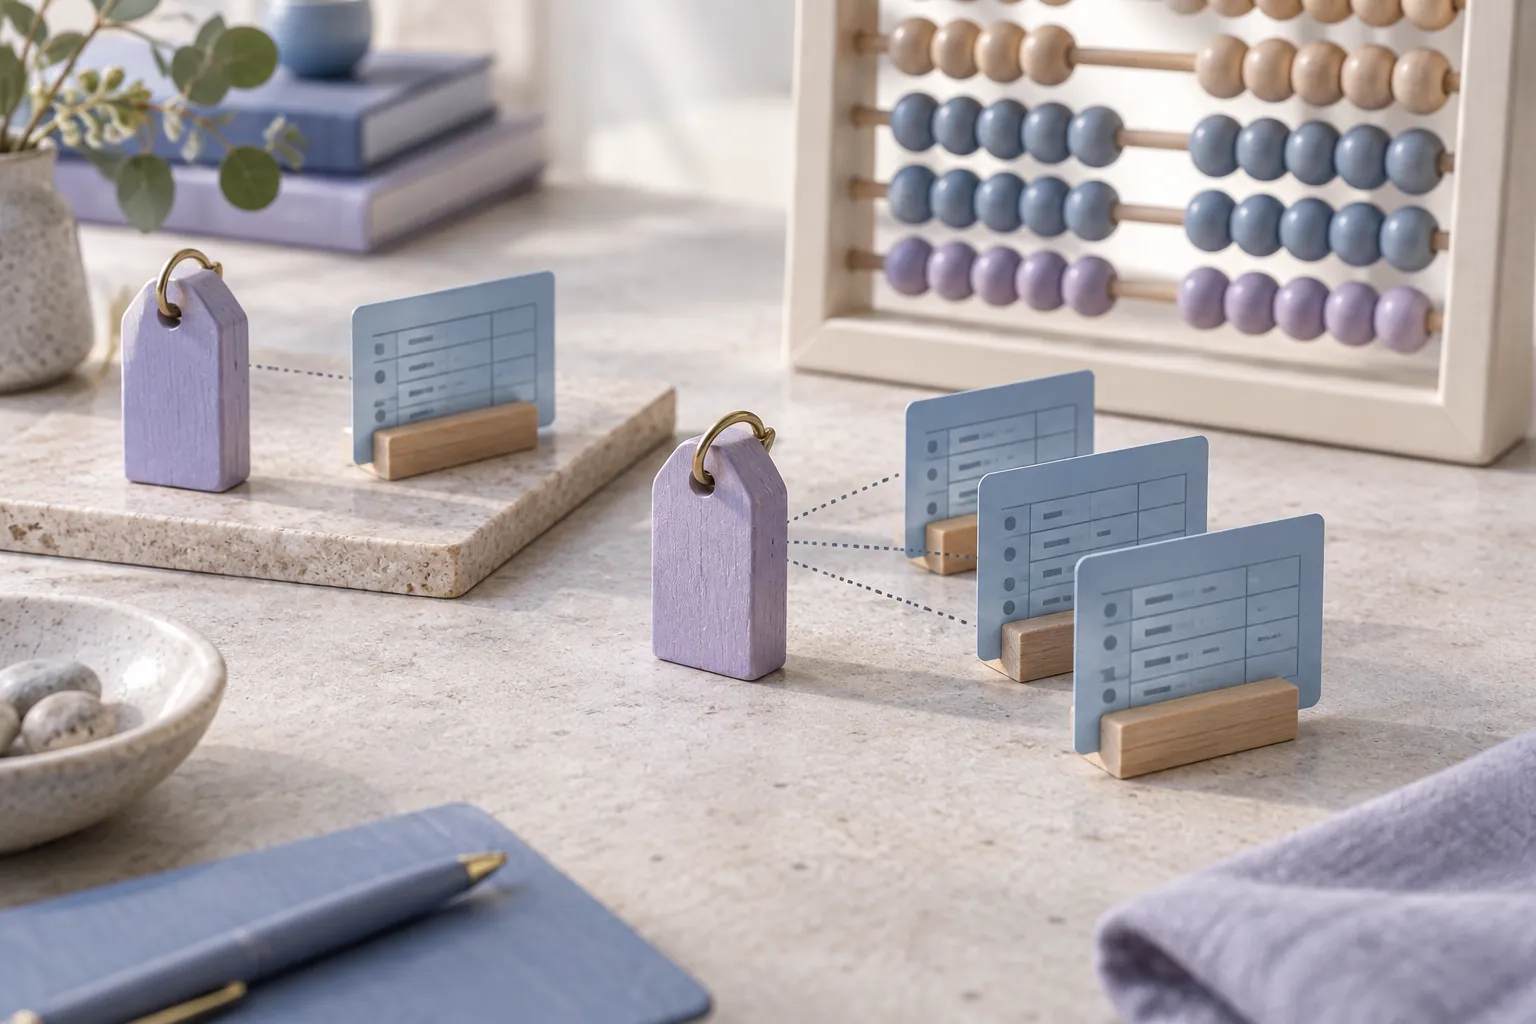
Keep records according to the join mode and review unmatched cases separately. Distinguishable output columns support later filtering and import preparation.
Explore the available features and choose what your table needs next.
Select one or more corresponding key fields in each table.
Use in the toolChoose how to join and which records should appear in the output.
Use in the toolEstimate row counts before execution and explicitly confirm potentially expanding joins.
Use in the toolFind records without a matching key so you can correct or complete the source data.
Use in the toolDisambiguate colliding column names instead of overwriting existing content.
Use in the toolRetain original source information to trace where joined records came from.
Use in the toolConfirm the input, inspect changes, and save the output you need.
Choose a CSV or TSV file, or paste a table. Check the delimiter, headers, and preview before confirming the full import.
Select corresponding keys in tables A and B, choose a join mode, and inspect the projected output. Confirm the estimate before reviewing matched and unmatched records.
Choose the result or report and CSV or TSV format. Review the export summary and protection count, then confirm download or copy.
Join CSV files combines records horizontally by a key you select. A product table might contain SKU and Name while a supplier lookup contains Product ID and Delivery Region. A join can place the related fields together even when the two identifier columns have different names. The relationship comes from their values and your field selection, not from a guessed interpretation of column labels. If you only need to append all records below one another, use the separate merge tool.
Import and confirm the primary table A and supplementary table B. Select the matching fields on each side in corresponding order. For a composite key, the first selected field on A corresponds to the first selected field on B, and so on. The number of selected components must match. Use all the components needed to identify the relationship: joining on SKU alone can be too broad if the real identity is SKU together with Region or Version.
Keep every record from A produces a result for every primary record, adding fields from B when a match exists. For an A record without a match, the B fields are missing. This is appropriate when A defines the population you must retain, such as all products in a catalog, and B supplies optional attributes. It does not mean every primary record was successfully matched. Inspect the unmatched A report to see the remaining gaps.
Only records matching on both sides excludes unmatched records from the joined table. It can answer a question about the overlap between two datasets, but it deliberately reduces the population. Keep every record from both tables also includes B records with no matching A record, with missing A fields. The unmatched reports remain available independently of the main joined result. A missing match is a data relationship outcome, not a generic system failure or proof that a record is invalid.
Repeated keys can multiply records. If one key occurs twice in A and three times in B, all matching combinations produce six output rows for that key. This can be correct for some relationships and very wrong for others. The workbench computes the projected output size before running an accepted join and surfaces duplicate-key information. Many-to-many combinations require their own explicit allowance. You can instead return to the sources and resolve duplicates or choose a more specific composite key.
The first attempt shows a projection for review. Check the count, the selected keep mode, and the duplicate situation, then confirm the join and run again. If the projection exceeds the output record or cell limit, the operation remains blocked. Permission for all combinations does not bypass scale limits. The estimate includes the unmatched rows required by your selected mode, so it can be compared directly with the eventual output total. No duplicate match is resolved by choosing a random row.
Empty and missing key components do not match one another. Two records lacking a product identifier are not evidence of the same product. The string zero is a populated key, while a blank string is not. Ignore case and Trim surrounding whitespace are visible matching options; they are off by default. Enabling them changes the equality test but does not rewrite the values displayed in either source. Original values and source positions remain attached to the resulting records.
Columns from B are appended to A. If a name already exists, the B column receives a source suffix such as _B, with additional disambiguation if necessary. The workbench does not silently overwrite A's value, even if a similarly named B field contains a different value. Matching key columns from B are also retained, making it possible to inspect both original spellings. Review the final names before using the column mapper to create a destination-specific layout.
Suppose A has two rows for code 001, representing two catalog variants, and one row with no code. B has three rows for 001, representing three delivery regions, and one row with no code. Keeping every record from both tables projects eight rows: six valid combinations for 001, one unmatched A record, and one unmatched B record. The empty-key rows do not combine into one row merely because both are blank.
If you expected only one row per product, the six combinations reveal that the chosen key is not sufficient for that expectation. Stop and choose an additional field, reduce B to a single justified record per code, or change the task. If you actually need every variant and region combination, allow the many-to-many relationship and confirm the projection. The final count should then equal eight, and the unmatched reports should each contain one record. This explicit check prevents later totals from being inflated without notice.
The output summary separates matched combinations from records found only in A or only in B. Matched combinations are output rows, not necessarily a count of distinct entities. Duplicate-key reports identify repeated relationships, and source locations help trace each combination to its contributing records. Use the grid to inspect cases with suffixes, missing fields, and repeated keys. A search in the grid is a viewing aid; it does not change which combinations the join produced.
When exporting, choose the full result or an unmatched report deliberately. An archive can retain all supporting outputs together with a file list. CSV cannot distinguish every internal missing-value state, so missing join fields become empty fields on export. Spreadsheet protection may prefix formula-like values and reports the number affected. Verification rereads the generated text before a download is made. This checks serialization consistency; it does not certify that your selected keys represent the intended business relationship.
Yes. Choose the identifier field on each side and the fields to bring into the result. The two key columns can have different names. Check whether the key is unique: several matches can produce several output records. Review unmatched rows rather than assuming that a blank returned field means the original value was blank.
Yes. Choose the corresponding fields separately on A and B. For example, SKU can match Product ID when you have established that both represent the same identifier. Composite keys also allow differently named components. Their selection order matters, so check the small order numbers shown with the selected fields before confirming the result.
A key can match multiple records on the other side. Each retained combination becomes a separate row. A two-by-three match therefore produces six combinations. This is not automatically an error, but it must agree with the unit you want one output row to represent. Check the projection and duplicate report instead of deleting repeated output rows without understanding their origin.
Exact text comparison preserves spaces, letter case, and leading zeros. The value 001 differs from 1, and “Blue ” differs from “Blue”. Inspect the full cell text and confirm the selected columns. Enable only the normalization rules appropriate for the identifier. A different Unicode representation can still remain different; the tool does not perform fuzzy identity matching.
Yes. The result includes separate Only in A and Only in B tables. Choose the intended report in the export dialog rather than relying on which tab happens to be visible. Each report preserves the columns of its own source table. This is useful when sending exceptions back to a source owner without including all matched combinations.
No. Joining creates an in-memory result and an optional new download. It does not connect to a database, execute spreadsheet formulas, or update the source files. Apply the result to continue within this session, or export a new copy. Keep an independent copy before refreshing the page because the current version does not persist the full session to device storage or the cloud.
Start with a sample to learn the workflow, then process your own files.